diff --git a/.github/workflows/lock.yml b/.github/workflows/lock.yml
new file mode 100644
index 000000000..6984af78f
--- /dev/null
+++ b/.github/workflows/lock.yml
@@ -0,0 +1,13 @@
+name: Lock closed issue
+
+on:
+ issues:
+ types: [closed]
+
+jobs:
+ lock:
+ runs-on: ubuntu-latest
+ steps:
+ - uses: OSDKDev/lock-issues@v1.1
+ with:
+ repo-token: "${{ secrets.GITHUB_TOKEN }}"
diff --git a/2-Regression/2-Data/translations/README.es.md b/2-Regression/2-Data/translations/README.es.md
new file mode 100644
index 000000000..2e7e6e3e8
--- /dev/null
+++ b/2-Regression/2-Data/translations/README.es.md
@@ -0,0 +1,207 @@
+# Construye un modelo de regresión usando Scikit-learn: prepara y visualiza los datos
+
+
+
+Infografía por [Dasani Madipalli](https://twitter.com/dasani_decoded)
+
+## [Examen previo a la lección](https://white-water-09ec41f0f.azurestaticapps.net/quiz/11/)
+
+> ### [Esta lección se encuentra disponible en R!](../solution/R/lesson_2-R.ipynb)
+
+## Introducción
+
+Ahora que has configurado las herramientas necesarias para iniciar el trabajo con la construcción de modelo de aprendizaje automático con Scikit-learn, estás listo para comenzar a realizar preguntas a tus datos. Mientras trabajas con los datos y aplicas soluciones de ML, es muy importante entender cómo realizar las preguntas correctas para desbloquear el potencial de tu conunto de datos.
+
+En esta lección, aprenderás:
+
+- Cómo preparar tus datos para la construcción de modelos.
+- Cómo usar Matplotlib para visualización de datos.
+
+[](https://youtu.be/11AnOn_OAcE "Video de preparación y visualizción de datos - ¡Clic para ver!")
+> 🎥 Da clic en la imagen superior para ver un video de los aspectos clave de esta lección
+
+
+## Realizando la pregunta correcta a tus datos
+
+La pregunta para la cual necesitas respuesta determinará qué tipo de algoritmos de ML requerirás. Y la calidad de la respuesta que obtendas será altamente dependiente de la naturaleza de tus datos.
+
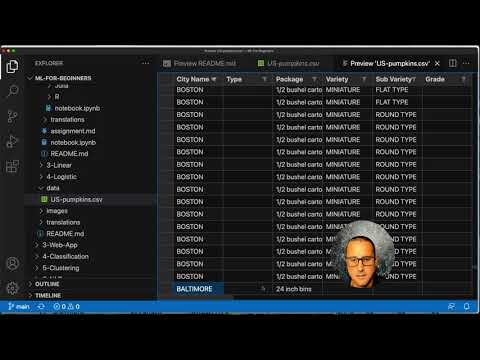
+Echa un vistazo a los [datos](../../data/US-pumpkins.csv) provistos para esta lección. Puedes abrir este archivo .csv en VS Code. Un vistazo rápido muestra inmediatamente que existen campos en blanco y una mezcla de datos numéricos y de cadena. También hay una columna extraña llamada 'Package' donde los datos están mezclados entre los valores 'sacks', 'bins' y otros. Los datos de hecho, son un pequeño desastre.
+
+De hecho, no es muy común obtener un conjunto de datos que esté totalmente listo para su uso en un modelo de ML. En esta lección, aprenderás cómo preparar un conjunto de datos en crudo usando librerías estándares de Python. También aprenderás varias técnicas para visualizar los datos.
+
+## Caso de estudio: 'El mercado de calabazas'
+
+En este directorio encontrarás un archivo .cvs in la raíz del directorio `data` llamado [US-pumpkins.csv](../../data/US-pumpkins.csv), el cual incluye 1757 líneas de datos acerca del mercado de calabazas, ordenados en agrupaciones por ciudad. Estos son loas datos extraídos de [Reportes estándar de mercados terminales de cultivos especializados](https://www.marketnews.usda.gov/mnp/fv-report-config-step1?type=termPrice) distribuido por el Departamento de Agricultura de los Estados Unidos.
+
+### Preparando los datos
+
+Estos datos son de dominio público. Puede ser descargado en varios archivos por separado, por ciudad, desde el sitio web de USDA. para evitar demasiados archivos por separado, hemos concatenado todos los datos de ciudad en una hoja de cálculo, así ya hemos _preparado_ los datos un poco. Lo siguiente es dar un vistazo más a fondo a los datos.
+
+### Los datos de las calabazas - conclusiones iniciales
+
+¿Qué notas acerca de los datos? Ya has visto que hay una mezcla de cadenas, números, blancos y valores extraños a los cuales debes encontrarle sentido.
+
+¿Qué preguntas puedes hacerle a los datos usando una técnica de regresión? Qué tal el "predecir el precio de la venta de calabaza durante un mes dado". Viendo nuevamente los datos, hay algunos cambios que necesitas hacer para crear las estructuras de datos necesarias para la tarea.
+## Ejercicio - Analiza los datos de la calabaza
+
+Usemos [Pandas](https://pandas.pydata.org/), (el nombre es un acrónimo de `Python Data Analysis`) a tool very useful for shaping data, to analyze and prepare this pumpkin data.
+
+### Primero, revisa las fechas faltantes
+
+Necesitarás realizar algunos pasos para revisar las fechas faltantes:
+
+1. Convertir las fechas a formato de mes (las fechas están en formato de EE.UU., por lo que el formato es `MM/DD/YYYY`).
+2. Extrae el mes en una nueva columna.
+
+Abre el archivo _notebook.ipynb_ en Visual Studio Code e importa la hoja de cálculo en un nuevo dataframe de Pandas.
+
+1. Usa la función `head()` para visualizar las primeras cinco filas.
+
+ ```python
+ import pandas as pd
+ pumpkins = pd.read_csv('../data/US-pumpkins.csv')
+ pumpkins.head()
+ ```
+
+ ✅ ¿Qué función usarías para ver las últimas cinco filas?
+
+1. Revisa si existen datos faltantes en el dataframe actual:
+
+ ```python
+ pumpkins.isnull().sum()
+ ```
+
+ Hay datos faltabtes, pero quizá no importen para la tarea en cuestión.
+
+1. Para facilitar el trabajo con tu dataframe, elimina varias de sus columnas usando `drop()`, manteniendo sólo las columnas que necesitas:
+
+ ```python
+ new_columns = ['Package', 'Month', 'Low Price', 'High Price', 'Date']
+ pumpkins = pumpkins.drop([c for c in pumpkins.columns if c not in new_columns], axis=1)
+ ```
+
+### Segundo, determina el precio promedio de la calabaza
+
+Piensa en cómo determinar el precio promedio de la calabaza en un mes dado. ¿Qué columnas eligirás para esa tarea? Pista: necesitarás 3 columnas.
+
+Solución: toma el promedio de las columnas `Low Price` y `High Price` para poblar la nueva columna `Price` y convierte la columna `Date` para mostrar únicamente el mes, Afortunadamente, de acuerdo a la revisión de arriba, no hay datos faltantes para las fechas o precios.
+
+1. Para calcular el promedio, agrega el siguiente código:
+
+ ```python
+ price = (pumpkins['Low Price'] + pumpkins['High Price']) / 2
+
+ month = pd.DatetimeIndex(pumpkins['Date']).month
+
+ ```
+
+ ✅ Siéntete libre de imprimir cualquier dato que desees verificar, usando `print(month)`.
+
+2. Ahora, copia tus datos convertidos en un nuevo dataframe de Pandas:
+
+ ```python
+ new_pumpkins = pd.DataFrame({'Month': month, 'Package': pumpkins['Package'], 'Low Price': pumpkins['Low Price'],'High Price': pumpkins['High Price'], 'Price': price})
+ ```
+
+ Imprimir tu dataframe te mostrará un conjunto de datos limpio y ordenado, en el cual puedes construir tu nuevo modelo de regresión.
+
+### ¡Pero espera!, Hay algo raro aquí
+
+Si observas la columna `Package`, las calabazas se venden en distintas configuraciones. Algunas son vendidas en medidas de '1 1/9 bushel', y otras en '1/2 bushel', algunas por pieza, algunas por libra y otras en grandes cajas de ancho variable.
+
+> Las calabazas parecen muy difíciles de pesar consistentemente.
+
+Indagando en los datos originales, es interesante que cualquiera con el valor `Unit of Sale` igualado a 'EACH' o 'PER BIN' también tiene el tipo de `Package` por pulgada, por cesto, o 'each'. Las calabazas parecen muy difíciles de pesar consistentemente, por lo que las filtraremos seleccionando solo aquellas calabazas con el string 'bushel' en su columna `Package`.
+
+1. Agrega un filtro al inicio del archivo, debajo de la importación inicial del .csv:
+
+ ```python
+ pumpkins = pumpkins[pumpkins['Package'].str.contains('bushel', case=True, regex=True)]
+ ```
+
+ Si imprimes los datos ahora, puedes ver que solo estás obteniendo alrededor de 415 filas de datos que contienen calabazas por fanegas.
+
+### ¡Pero espera! Aún hay algo más que hacer
+
+¿Notaste que la cantidad de fanegas varían por fila? Necesitas normalizar el precio para así mostrar el precio por fanega, así que haz los cálculos para estandarizarlo.
+
+1. Agrega estas líneas después del bloque para así crear el dataframe new_pumpkins:
+
+ ```python
+ new_pumpkins.loc[new_pumpkins['Package'].str.contains('1 1/9'), 'Price'] = price/(1 + 1/9)
+
+ new_pumpkins.loc[new_pumpkins['Package'].str.contains('1/2'), 'Price'] = price/(1/2)
+ ```
+
+✅ De acuerdo a [The Spruce Eats](https://www.thespruceeats.com/how-much-is-a-bushel-1389308), el peso de una fanega depende del tipo de producto, ya que es una medida de volumen. "Una fanega de tomates, por ejemplo, se supone pese 56 libras... Las hojas y verduras usan más espacio con menos peso, por lo que una fanega de espinaca es de sólo 20 libras." ¡Todo es tan complicado! No nos molestemos en realizar una conversión fanega-a-libra, y en su lugar hagámosla por precio de fanega. ¡Todo este estudio de las fanegas de calabazas nos mostrará cuán importante es comprender la naturaleza de tus datos!
+
+Ahora, puedes analizar el precio por unidad basándote en su medida de fanega. Si imprimes los datos una vez más, verás que ya están estandarizados.
+
+✅ ¿Notaste que las calabazas vendidas por media fanega son más caras? ¿Puedes descubrir la razón? Ayuda: Las calabazas pequeñas son mucho más caras que las grandes, probablemente porque hay muchas más de ellas por fanega, dado el espacio sin usar dejado por una calabaza grande.
+
+## Estrategias de visualización
+
+parte del rol de un científico de datos es el demostrar la calidad y naturaleza de los dato con los que está trabajando. Para hacerlo, usualmente crean visualizaciones interesantes, o gráficos, grafos, y gráficas, mostrando distintos aspectos de los datos. De esta forma, son capaces de mostrar visualmente las relaciones y brechas de que otra forma son difíciles de descubrir.
+
+Las visualizaciones también ayudan a determinar la técnica de aprendizaje automático más apropiada para los datos. Por ejemplo, un gráfico de dispersión que parece seguir una línea, indica que los datos son un buen candidato para un ejercicio de regresión lineal.
+
+Una librería de visualización de datos que funciona bien en los notebooks de Jupyter es [Matplotlib](https://matplotlib.org/) (la cual también viste en la lección anterior).
+
+> Obtén más experiencia con la visualización de datos en [estos tutoriales](https://docs.microsoft.com/learn/modules/explore-analyze-data-with-python?WT.mc_id=academic-15963-cxa).
+
+## Ejercicio - experimenta con Matplotlib
+
+Intenta crear algunas gráficas básicas para mostrar el nuevo dataframe que acabas de crear. ¿Qué mostraría una gráfica de línea básica?
+
+1. Importa Matplotlib al inicio del archivo, debajo de la importación de Pandas:
+
+ ```python
+ import matplotlib.pyplot as plt
+ ```
+
+1. Vuelve a correr todo el notebook para refrescarlo.
+1. Al final del notebook, agrega una celda para graficar los datos como una caja:
+
+ ```python
+ price = new_pumpkins.Price
+ month = new_pumpkins.Month
+ plt.scatter(price, month)
+ plt.show()
+ ```
+
+ 
+
+ ¿La gráfica es útil? ¿Hay algo acerca de ésta que te sorprenda?
+
+ No es particularmente útil ya que todo lo que hace es mostrar tus datos como puntos dispersos en un mes dado.
+
+### Hacerlo útil
+
+Para obtener gráficas para mostrar datos útiles, necesitas agrupar los datos de alguna forma. Probemos creando un gráfico donde el eje y muestre los meses y los datos demuestren la distribución de los datos.
+
+1. Agrega una celda para crear una gráfica de barras agrupadas:
+
+ ```python
+ new_pumpkins.groupby(['Month'])['Price'].mean().plot(kind='bar')
+ plt.ylabel("Pumpkin Price")
+ ```
+
+ 
+
+ ¡Esta es una visualización de datos más útil! Parece indicar que el precio más alto para las calabazas ocurre en Septiembre y Octubre. ¿Cumple esto con tus expectativas? ¿por qué sí o por qué no?
+
+---
+
+## 🚀Desafío
+
+Explora los distintos tipos de visualización que ofrece Matplotlib. ¿Qué tipos son los más apropiados para problemas de regresión?
+
+## [Examen posterior a la lección](https://white-water-09ec41f0f.azurestaticapps.net/quiz/12/)
+
+## Revisión y autoestudio
+
+Dale un vistazo a las distintas forma de visualizar los datos. Haz un lista de las distintas librerías disponibles y nota cuales son mejores para cierto tipo de tareas, por ejemplo visualizaciones 2D vs visualizaciones 3D. ¿Qué descubriste?
+
+## Asignación
+
+[Explorando la visualización](assignment.es.md)
diff --git a/2-Regression/3-Linear/README.md b/2-Regression/3-Linear/README.md
index c2fe13893..40a07fce2 100644
--- a/2-Regression/3-Linear/README.md
+++ b/2-Regression/3-Linear/README.md
@@ -1,4 +1,4 @@
-# Build a regression model using Scikit-learn: regression two ways
+# Build a regression model using Scikit-learn: regression four ways

> Infographic by [Dasani Madipalli](https://twitter.com/dasani_decoded)
@@ -7,15 +7,17 @@
> ### [This lesson is available in R!](./solution/R/lesson_3-R.ipynb)
### Introduction
-So far you have explored what regression is with sample data gathered from the pumpkin pricing dataset that we will use throughout this lesson. You have also visualized it using Matplotlib.
+So far you have explored what regression is with sample data gathered from the pumpkin pricing dataset that we will use throughout this lesson. You have also visualized it using Matplotlib.
-Now you are ready to dive deeper into regression for ML. In this lesson, you will learn more about two types of regression: _basic linear regression_ and _polynomial regression_, along with some of the math underlying these techniques.
+Now you are ready to dive deeper into regression for ML. While visualization allows you to make sense of data, the real power of Machine Learning comes from _training models_. Models are trained on historic data to automatically capture data dependencies, and they allow you to predict outcomes for new data, which the model has not seem before.
+
+In this lesson, you will learn more about two types of regression: _basic linear regression_ and _polynomial regression_, along with some of the math underlying these techniques. Those models will allow us to predict pumpkin prices depending on different input data.
> Throughout this curriculum, we assume minimal knowledge of math, and seek to make it accessible for students coming from other fields, so watch for notes, 🧮 callouts, diagrams, and other learning tools to aid in comprehension.
### Prerequisite
-You should be familiar by now with the structure of the pumpkin data that we are examining. You can find it preloaded and pre-cleaned in this lesson's _notebook.ipynb_ file. In the file, the pumpkin price is displayed per bushel in a new dataframe. Make sure you can run these notebooks in kernels in Visual Studio Code.
+You should be familiar by now with the structure of the pumpkin data that we are examining. You can find it preloaded and pre-cleaned in this lesson's _notebook.ipynb_ file. In the file, the pumpkin price is displayed per bushel in a new data frame. Make sure you can run these notebooks in kernels in Visual Studio Code.
### Preparation
@@ -26,7 +28,7 @@ As a reminder, you are loading this data so as to ask questions of it.
- Should I buy them in half-bushel baskets or by the 1 1/9 bushel box?
Let's keep digging into this data.
-In the previous lesson, you created a Pandas dataframe and populated it with part of the original dataset, standardizing the pricing by the bushel. By doing that, however, you were only able to gather about 400 datapoints and only for the fall months.
+In the previous lesson, you created a Pandas data frame and populated it with part of the original dataset, standardizing the pricing by the bushel. By doing that, however, you were only able to gather about 400 datapoints and only for the fall months.
Take a look at the data that we preloaded in this lesson's accompanying notebook. The data is preloaded and an initial scatterplot is charted to show month data. Maybe we can get a little more detail about the nature of the data by cleaning it more.
@@ -71,251 +73,253 @@ One more term to understand is the **Correlation Coefficient** between given X a
A good linear regression model will be one that has a high (nearer to 1 than 0) Correlation Coefficient using the Least-Squares Regression method with a line of regression.
-✅ Run the notebook accompanying this lesson and look at the City to Price scatterplot. Does the data associating City to Price for pumpkin sales seem to have high or low correlation, according to your visual interpretation of the scatterplot?
-
+✅ Run the notebook accompanying this lesson and look at the Month to Price scatterplot. Does the data associating Month to Price for pumpkin sales seem to have high or low correlation, according to your visual interpretation of the scatterplot? Does that change if you use more fine-grained measure instead of `Month`, eg. *day of the year* (i.e. number of days since the beginning of the year)?
-## Prepare your data for regression
+In the code below, we will assume that we have cleaned up the data, and obtained a data frame called `new_pumpkins`, similar to the following:
-Now that you have an understanding of the math behind this exercise, create a Regression model to see if you can predict which package of pumpkins will have the best pumpkin prices. Someone buying pumpkins for a holiday pumpkin patch might want this information to be able to optimize their purchases of pumpkin packages for the patch.
+ID | Month | DayOfYear | Variety | City | Package | Low Price | High Price | Price
+---|-------|-----------|---------|------|---------|-----------|------------|-------
+70 | 9 | 267 | PIE TYPE | BALTIMORE | 1 1/9 bushel cartons | 15.0 | 15.0 | 13.636364
+71 | 9 | 267 | PIE TYPE | BALTIMORE | 1 1/9 bushel cartons | 18.0 | 18.0 | 16.363636
+72 | 10 | 274 | PIE TYPE | BALTIMORE | 1 1/9 bushel cartons | 18.0 | 18.0 | 16.363636
+73 | 10 | 274 | PIE TYPE | BALTIMORE | 1 1/9 bushel cartons | 17.0 | 17.0 | 15.454545
+74 | 10 | 281 | PIE TYPE | BALTIMORE | 1 1/9 bushel cartons | 15.0 | 15.0 | 13.636364
-Since you'll use Scikit-learn, there's no reason to do this by hand (although you could!). In the main data-processing block of your lesson notebook, add a library from Scikit-learn to automatically convert all string data to numbers:
+> The code to clean the data is available in [`notebook.ipynb`](notebook.ipynb). We have performed the same cleaning steps as in the previous lesson, and have calculated `DayOfYear` column using the following expression:
```python
-from sklearn.preprocessing import LabelEncoder
-
-new_pumpkins.iloc[:, 0:-1] = new_pumpkins.iloc[:, 0:-1].apply(LabelEncoder().fit_transform)
+day_of_year = pd.to_datetime(pumpkins['Date']).apply(lambda dt: (dt-datetime(dt.year,1,1)).days)
```
-If you look at the new_pumpkins dataframe now, you see that all the strings are now numeric. This makes it harder for you to read but much more intelligible for Scikit-learn!
-Now you can make more educated decisions (not just based on eyeballing a scatterplot) about the data that is best suited to regression.
+Now that you have an understanding of the math behind linear regression, let's create a Regression model to see if we can predict which package of pumpkins will have the best pumpkin prices. Someone buying pumpkins for a holiday pumpkin patch might want this information to be able to optimize their purchases of pumpkin packages for the patch.
-Try to find a good correlation between two points of your data to potentially build a good predictive model. As it turns out, there's only weak correlation between the City and Price:
+## Looking for Correlation
-```python
-print(new_pumpkins['City'].corr(new_pumpkins['Price']))
-0.32363971816089226
-```
+From the previous lesson you have probably seen that the average price for different months looks like this:
-However there's a bit better correlation between the Package and its Price. That makes sense, right? Normally, the bigger the produce box, the higher the price.
+
+
+This suggests that there should be some correlation, and we can try training linear regression model to predict the relationship between `Month` and `Price`, or between `DayOfYear` and `Price`. Here is the scatter plot that shows the latter relationship:
+
+
+
+It looks like there are different clusters of prices corresponding to different pumpkin varieties. To confirm this hypothesis, let's plot each pumpkin category using a different color. By passing an `ax` parameter to the `scatter` plotting function we can plot all points on the same graph:
```python
-print(new_pumpkins['Package'].corr(new_pumpkins['Price']))
-0.6061712937226021
+ax=None
+colors = ['red','blue','green','yellow']
+for i,var in enumerate(new_pumpkins['Variety'].unique()):
+ df = new_pumpkins[new_pumpkins['Variety']==var]
+ ax = df.plot.scatter('DayOfYear','Price',ax=ax,c=colors[i],label=var)
```
-A good question to ask of this data will be: 'What price can I expect of a given pumpkin package?'
+
-Let's build this regression model
+Our investigation suggests that variety has more effect on the overall price than the actual selling date. So let us focus for the moment only on one pumpkin variety, and see what effect the date has on the price:
+
+```python
+pie_pumpkins = new_pumpkins[new_pumpkins['Variety']=='PIE TYPE']
+pie_pumpkins.plot.scatter('DayOfYear','Price')
+```
+
-## Building a linear model
+If we now calculate the correlation between `Price` and `DayOfYear` using `corr` function, we will get something like `-0.27` - which means that training a predictive model makes sense.
-Before building your model, do one more tidy-up of your data. Drop any null data and check once more what the data looks like.
+> Before training a linear regression model, it is important to make sure that our data is clean. Linear regression does not work well with missing values, thus it makes sense to get rid of all empty cells:
```python
-new_pumpkins.dropna(inplace=True)
-new_pumpkins.info()
+pie_pumpkins.dropna(inplace=True)
+pie_pumpkins.info()
```
-Then, create a new dataframe from this minimal set and print it out:
+Another approach would be to fill those empty values with mean values from the corresponding column.
-```python
-new_columns = ['Package', 'Price']
-lin_pumpkins = new_pumpkins.drop([c for c in new_pumpkins.columns if c not in new_columns], axis='columns')
+## Simple Linear Regression
-lin_pumpkins
-```
+To train our Linear Regression model, we will use the **Scikit-learn** library.
-```output
- Package Price
-70 0 13.636364
-71 0 16.363636
-72 0 16.363636
-73 0 15.454545
-74 0 13.636364
-... ... ...
-1738 2 30.000000
-1739 2 28.750000
-1740 2 25.750000
-1741 2 24.000000
-1742 2 24.000000
-415 rows × 2 columns
+```python
+from sklearn.linear_model import LinearRegression
+from sklearn.metrics import mean_squared_error
+from sklearn.model_selection import train_test_split
```
-1. Now you can assign your X and y coordinate data:
+We start by separating input values (features) and the expected output (label) into separate numpy arrays:
- ```python
- X = lin_pumpkins.values[:, :1]
- y = lin_pumpkins.values[:, 1:2]
- ```
-✅ What's going on here? You're using [Python slice notation](https://stackoverflow.com/questions/509211/understanding-slice-notation/509295#509295) to create arrays to populate `X` and `y`.
+```python
+X = pie_pumpkins['DayOfYear'].to_numpy().reshape(-1,1)
+y = pie_pumpkins['Price']
+```
-2. Next, start the regression model-building routines:
+> Note that we had to perform `reshape` on the input data in order for the Linear Regression package to understand it correctly. Linear Regression expects a 2D-array as an input, where each row of the array corresponds to a vector of input features. In our case, since we have only one input - we need an array with shape N×1, where N is the dataset size.
- ```python
- from sklearn.linear_model import LinearRegression
- from sklearn.metrics import r2_score, mean_squared_error, mean_absolute_error
- from sklearn.model_selection import train_test_split
+Then, we need to split the data into train and test datasets, so that we can validate our model after training:
- X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
- lin_reg = LinearRegression()
- lin_reg.fit(X_train,y_train)
+```python
+X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
+```
- pred = lin_reg.predict(X_test)
+Finally, training the actual Linear Regression model takes only two lines of code. We define the `LinearRegression` object, and fit it to our data using the `fit` method:
- accuracy_score = lin_reg.score(X_train,y_train)
- print('Model Accuracy: ', accuracy_score)
- ```
+```python
+lin_reg = LinearRegression()
+lin_reg.fit(X_train,y_train)
+```
- Because the correlation isn't particularly good, the model produced isn't terribly accurate.
+The `LinearRegression` object after `fit`-ting contains all the coefficients of the regression, which can be accessed using `.coef_` property. In our case, there is just one coefficient, which should be around `-0.017`. It means that prices seem to drop a bit with time, but not too much, around 2 cents per day. We can also access the intersection point of the regression with Y-axis using `lin_reg.intercept_` - it will be around `21` in our case, indicating the price at the beginning of the year.
- ```output
- Model Accuracy: 0.3315342327998987
- ```
+To see how accurate our model is, we can predict prices on a test dataset, and then measure how close our predictions are to the expected values. This can be done using mean square error (MSE) metrics, which is the mean of all squared differences between expected and predicted value.
-3. You can visualize the line that's drawn in the process:
+```python
+pred = lin_reg.predict(X_test)
- ```python
- plt.scatter(X_test, y_test, color='black')
- plt.plot(X_test, pred, color='blue', linewidth=3)
+mse = np.sqrt(mean_squared_error(y_test,pred))
+print(f'Mean error: {mse:3.3} ({mse/np.mean(pred)*100:3.3}%)')
+```
- plt.xlabel('Package')
- plt.ylabel('Price')
+Our error seems to be around 2 points, which is ~17%. Not too good. Another indicator of model quality is the **coefficient of determination**, which can be obtained like this:
- plt.show()
- ```
- 
+```python
+score = lin_reg.score(X_train,y_train)
+print('Model determination: ', score)
+```
+If the value is 0, it means that the model does not take input data into account, and acts as the *worst linear predictor*, which is simply a mean value of the result. The value of 1 means that we can perfectly predict all expected outputs. In our case, the coefficient is around 0.06, which is quite low.
-4. Test the model against a hypothetical variety:
+We can also plot the test data together with the regression line to better see how regression works in our case:
- ```python
- lin_reg.predict( np.array([ [2.75] ]) )
- ```
-
- The returned price for this mythological Variety is:
+```python
+plt.scatter(X_test,y_test)
+plt.plot(X_test,pred)
+```
- ```output
- array([[33.15655975]])
- ```
+
-That number makes sense, if the logic of the regression line holds true.
-🎃 Congratulations, you just created a model that can help predict the price of a few varieties of pumpkins. Your holiday pumpkin patch will be beautiful. But you can probably create a better model!
-## Polynomial regression
+## Polynomial Regression
-Another type of linear regression is polynomial regression. While sometimes there's a linear relationship between variables - the bigger the pumpkin in volume, the higher the price - sometimes these relationships can't be plotted as a plane or straight line.
+Another type of Linear Regression is Polynomial Regression. While sometimes there's a linear relationship between variables - the bigger the pumpkin in volume, the higher the price - sometimes these relationships can't be plotted as a plane or straight line.
-✅ Here are [some more examples](https://online.stat.psu.edu/stat501/lesson/9/9.8) of data that could use polynomial regression
+✅ Here are [some more examples](https://online.stat.psu.edu/stat501/lesson/9/9.8) of data that could use Polynomial Regression
-Take another look at the relationship between Variety to Price in the previous plot. Does this scatterplot seem like it should necessarily be analyzed by a straight line? Perhaps not. In this case, you can try polynomial regression.
+Take another look at the relationship between Date and Price. Does this scatterplot seem like it should necessarily be analyzed by a straight line? Can't prices fluctuate? In this case, you can try polynomial regression.
✅ Polynomials are mathematical expressions that might consist of one or more variables and coefficients
-Polynomial regression creates a curved line to better fit nonlinear data.
-
-1. Let's recreate a dataframe populated with a segment of the original pumpkin data:
+Polynomial regression creates a curved line to better fit nonlinear data. In our case, if we include a squared `DayOfYear` variable into input data, we should be able to fit our data with a parabolic curve, which will have a minimum at a certain point within the year.
- ```python
- new_columns = ['Variety', 'Package', 'City', 'Month', 'Price']
- poly_pumpkins = new_pumpkins.drop([c for c in new_pumpkins.columns if c not in new_columns], axis='columns')
+Scikit-learn includes a helpful [pipeline API](https://scikit-learn.org/stable/modules/generated/sklearn.pipeline.make_pipeline.html?highlight=pipeline#sklearn.pipeline.make_pipeline) to combine different steps of data processing together. A **pipeline** is a chain of **estimators**. In our case, we will create a pipeline that first adds polynomial features to our model, and then trains the regression:
- poly_pumpkins
- ```
+```python
+from sklearn.preprocessing import PolynomialFeatures
+from sklearn.pipeline import make_pipeline
-A good way to visualize the correlations between data in dataframes is to display it in a 'coolwarm' chart:
+pipeline = make_pipeline(PolynomialFeatures(2), LinearRegression())
-2. Use the `Background_gradient()` method with `coolwarm` as its argument value:
+pipeline.fit(X_train,y_train)
+```
- ```python
- corr = poly_pumpkins.corr()
- corr.style.background_gradient(cmap='coolwarm')
- ```
- This code creates a heatmap:
- 
+Using `PolynomialFeatures(2)` means that we will include all second-degree polynomials from the input data. In our case it will just mean `DayOfYear`2, but given two input variables X and Y, this will add X2, XY and Y2. We may also use higher degree polynomials if we want.
-Looking at this chart, you can visualize the good correlation between Package and Price. So you should be able to create a somewhat better model than the last one.
-### Create a pipeline
+Pipelines can be used in the same manner as the original `LinearRegression` object, i.e. we can `fit` the pipeline, and then use `predict` to get the prediction results. Here is the graph showing test data, and the approximation curve:
+
+
-Scikit-learn includes a helpful API for building polynomial regression models - the `make_pipeline` [API](https://scikit-learn.org/stable/modules/generated/sklearn.pipeline.make_pipeline.html?highlight=pipeline#sklearn.pipeline.make_pipeline). A 'pipeline' is created which is a chain of estimators. In this case, the pipeline includes polynomial features, or predictions that form a nonlinear path.
+Using Polynomial Regression, we can get slightly lower MSE and higher determination, but not significantly. We need to take into account other features!
-1. Build out the X and y columns:
+> You can see that the minimal pumpkin prices are observed somewhere around Halloween. How can you explain this?
- ```python
- X=poly_pumpkins.iloc[:,3:4].values
- y=poly_pumpkins.iloc[:,4:5].values
- ```
+🎃 Congratulations, you just created a model that can help predict the price of pie pumpkins. You can probably repeat the same procedure for all pumpkin types, but that would be tedious. Let's learn now how to take pumpkin variety into account in our model!
-2. Create the pipeline by calling the `make_pipeline()` method:
+## Categorical Features
- ```python
- from sklearn.preprocessing import PolynomialFeatures
- from sklearn.pipeline import make_pipeline
+In the ideal world, we want to be able to predict prices for different pumpkin varieties using the same model. However, the `Variety` column is somewhat different from columns like `Month`, because it contains non-numeric values. Such columns are called **categorical**.
- pipeline = make_pipeline(PolynomialFeatures(4), LinearRegression())
+Here you can see how average price depends on variety:
- X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
+
- pipeline.fit(np.array(X_train), y_train)
+To take variety into account, we first need to convert it to numeric form, or **encode** it. There are several way we can do it:
- y_pred=pipeline.predict(X_test)
- ```
+* Simple **numeric encoding** will build a table of different varieties, and then replace the variety name by an index in that table. This is not the best idea for linear regression, because linear regression takes the actual numeric value of the index, and adds it to the result, multiplying by some coefficient. In our case, the relationship between the index number and the price is clearly non-linear, even if we make sure that indices are ordered in some specific way.
+* **One-hot encoding** will replace the `Variety` column by 4 different columns, one for each variety. Each column will contain `1` if the corresponding row is of a given variety, and `0` otherwise. This means that there will be four coefficients in linear regression, one for each pumpkin variety, responsible for "starting price" (or rather "additional price") for that particular variety.
-### Create a sequence
+The code below shows how we can one-hot encode a variety:
-At this point, you need to create a new dataframe with _sorted_ data so that the pipeline can create a sequence.
+```python
+pd.get_dummies(new_pumpkins['Variety'])
+```
-Add the following code:
+ ID | FAIRYTALE | MINIATURE | MIXED HEIRLOOM VARIETIES | PIE TYPE
+----|-----------|-----------|--------------------------|----------
+70 | 0 | 0 | 0 | 1
+71 | 0 | 0 | 0 | 1
+... | ... | ... | ... | ...
+1738 | 0 | 1 | 0 | 0
+1739 | 0 | 1 | 0 | 0
+1740 | 0 | 1 | 0 | 0
+1741 | 0 | 1 | 0 | 0
+1742 | 0 | 1 | 0 | 0
- ```python
- df = pd.DataFrame({'x': X_test[:,0], 'y': y_pred[:,0]})
- df.sort_values(by='x',inplace = True)
- points = pd.DataFrame(df).to_numpy()
+To train linear regression using one-hot encoded variety as input, we just need to initialize `X` and `y` data correctly:
- plt.plot(points[:, 0], points[:, 1],color="blue", linewidth=3)
- plt.xlabel('Package')
- plt.ylabel('Price')
- plt.scatter(X,y, color="black")
- plt.show()
- ```
+```python
+X = pd.get_dummies(new_pumpkins['Variety'])
+y = new_pumpkins['Price']
+```
-You created a new dataframe by calling `pd.DataFrame`. Then you sorted the values by calling `sort_values()`. Finally you created a polynomial plot:
+The rest of the code is the same as what we used above to train Linear Regression. If you try it, you will see that the mean squared error is about the same, but we get much higher coefficient of determination (~77%). To get even more accurate predictions, we can take more categorical features into account, as well as numeric features, such as `Month` or `DayOfYear`. To get one large array of features, we can use `join`:
-
+```python
+X = pd.get_dummies(new_pumpkins['Variety']) \
+ .join(new_pumpkins['Month']) \
+ .join(pd.get_dummies(new_pumpkins['City'])) \
+ .join(pd.get_dummies(new_pumpkins['Package']))
+y = new_pumpkins['Price']
+```
-You can see a curved line that fits your data better.
+Here we also take into account `City` and `Package` type, which gives us MSE 2.84 (10%), and determination 0.94!
-Let's check the model's accuracy:
+## Putting it all together
- ```python
- accuracy_score = pipeline.score(X_train,y_train)
- print('Model Accuracy: ', accuracy_score)
- ```
+To make the best model, we can use combined (one-hot encoded categorical + numeric) data from the above example together with Polynomial Regression. Here is the complete code for your convenience:
- And voila!
+```python
+# set up training data
+X = pd.get_dummies(new_pumpkins['Variety']) \
+ .join(new_pumpkins['Month']) \
+ .join(pd.get_dummies(new_pumpkins['City'])) \
+ .join(pd.get_dummies(new_pumpkins['Package']))
+y = new_pumpkins['Price']
- ```output
- Model Accuracy: 0.8537946517073784
- ```
+# make train-test split
+X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
-That's better! Try to predict a price:
+# setup and train the pipeline
+pipeline = make_pipeline(PolynomialFeatures(2), LinearRegression())
+pipeline.fit(X_train,y_train)
-### Do a prediction
+# predict results for test data
+pred = pipeline.predict(X_test)
-Can we input a new value and get a prediction?
+# calculate MSE and determination
+mse = np.sqrt(mean_squared_error(y_test,pred))
+print(f'Mean error: {mse:3.3} ({mse/np.mean(pred)*100:3.3}%)')
-Call `predict()` to make a prediction:
-
- ```python
- pipeline.predict( np.array([ [2.75] ]) )
- ```
- You are given this prediction:
+score = pipeline.score(X_train,y_train)
+print('Model determination: ', score)
+```
- ```output
- array([[46.34509342]])
- ```
+This should give us the best determination coefficient of almost 97%, and MSE=2.23 (~8% prediction error).
-It does make sense, given the plot! And, if this is a better model than the previous one, looking at the same data, you need to budget for these more expensive pumpkins!
+| Model | MSE | Determination |
+|-------|-----|---------------|
+| `DayOfYear` Linear | 2.77 (17.2%) | 0.07 |
+| `DayOfYear` Polynomial | 2.73 (17.0%) | 0.08 |
+| `Variety` Linear | 5.24 (19.7%) | 0.77 |
+| All features Linear | 2.84 (10.5%) | 0.94 |
+| All features Polynomial | 2.23 (8.25%) | 0.97 |
-🏆 Well done! You created two regression models in one lesson. In the final section on regression, you will learn about logistic regression to determine categories.
+🏆 Well done! You created four Regression models in one lesson, and improved the model quality to 97%. In the final section on Regression, you will learn about Logistic Regression to determine categories.
---
## 🚀Challenge
diff --git a/2-Regression/3-Linear/images/linear-results.png b/2-Regression/3-Linear/images/linear-results.png
new file mode 100644
index 000000000..05abe0025
Binary files /dev/null and b/2-Regression/3-Linear/images/linear-results.png differ
diff --git a/2-Regression/3-Linear/images/pie-pumpkins-scatter.png b/2-Regression/3-Linear/images/pie-pumpkins-scatter.png
new file mode 100644
index 000000000..f0a2af56b
Binary files /dev/null and b/2-Regression/3-Linear/images/pie-pumpkins-scatter.png differ
diff --git a/2-Regression/3-Linear/images/poly-results.png b/2-Regression/3-Linear/images/poly-results.png
new file mode 100644
index 000000000..6d1e96336
Binary files /dev/null and b/2-Regression/3-Linear/images/poly-results.png differ
diff --git a/2-Regression/3-Linear/images/price-by-variety.png b/2-Regression/3-Linear/images/price-by-variety.png
new file mode 100644
index 000000000..e5a15ca34
Binary files /dev/null and b/2-Regression/3-Linear/images/price-by-variety.png differ
diff --git a/2-Regression/3-Linear/images/scatter-dayofyear-color.png b/2-Regression/3-Linear/images/scatter-dayofyear-color.png
new file mode 100644
index 000000000..499b6f6dd
Binary files /dev/null and b/2-Regression/3-Linear/images/scatter-dayofyear-color.png differ
diff --git a/2-Regression/3-Linear/images/scatter-dayofyear.png b/2-Regression/3-Linear/images/scatter-dayofyear.png
new file mode 100644
index 000000000..d37356c25
Binary files /dev/null and b/2-Regression/3-Linear/images/scatter-dayofyear.png differ
diff --git a/2-Regression/3-Linear/notebook.ipynb b/2-Regression/3-Linear/notebook.ipynb
index adcbbce3a..2da56e5b6 100644
--- a/2-Regression/3-Linear/notebook.ipynb
+++ b/2-Regression/3-Linear/notebook.ipynb
@@ -1,28 +1,8 @@
{
- "metadata": {
- "language_info": {
- "codemirror_mode": {
- "name": "ipython",
- "version": 3
- },
- "file_extension": ".py",
- "mimetype": "text/x-python",
- "name": "python",
- "nbconvert_exporter": "python",
- "pygments_lexer": "ipython3",
- "version": "3.8.3-final"
- },
- "orig_nbformat": 2,
- "kernelspec": {
- "name": "python3",
- "display_name": "Python 3",
- "language": "python"
- }
- },
- "nbformat": 4,
- "nbformat_minor": 2,
"cells": [
{
+ "cell_type": "markdown",
+ "metadata": {},
"source": [
"## Pumpkin Pricing\n",
"\n",
@@ -32,9 +12,7 @@
"- Convert the date to a month\n",
"- Calculate the price to be an average of high and low prices\n",
"- Convert the price to reflect the pricing by bushel quantity"
- ],
- "cell_type": "markdown",
- "metadata": {}
+ ]
},
{
"cell_type": "code",
@@ -42,8 +20,175 @@
"metadata": {},
"outputs": [
{
- "output_type": "execute_result",
"data": {
+ "text/html": [
+ "
\n",
+ "\n",
+ "
\n",
+ " \n",
+ "
\n",
+ "
\n",
+ "
City Name
\n",
+ "
Type
\n",
+ "
Package
\n",
+ "
Variety
\n",
+ "
Sub Variety
\n",
+ "
Grade
\n",
+ "
Date
\n",
+ "
Low Price
\n",
+ "
High Price
\n",
+ "
Mostly Low
\n",
+ "
...
\n",
+ "
Unit of Sale
\n",
+ "
Quality
\n",
+ "
Condition
\n",
+ "
Appearance
\n",
+ "
Storage
\n",
+ "
Crop
\n",
+ "
Repack
\n",
+ "
Trans Mode
\n",
+ "
Unnamed: 24
\n",
+ "
Unnamed: 25
\n",
+ "
\n",
+ " \n",
+ " \n",
+ "
\n",
+ "
0
\n",
+ "
BALTIMORE
\n",
+ "
NaN
\n",
+ "
24 inch bins
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
4/29/17
\n",
+ "
270.0
\n",
+ "
280.0
\n",
+ "
270.0
\n",
+ "
...
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
E
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
\n",
+ "
\n",
+ "
1
\n",
+ "
BALTIMORE
\n",
+ "
NaN
\n",
+ "
24 inch bins
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
5/6/17
\n",
+ "
270.0
\n",
+ "
280.0
\n",
+ "
270.0
\n",
+ "
...
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
E
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
\n",
+ "
\n",
+ "
2
\n",
+ "
BALTIMORE
\n",
+ "
NaN
\n",
+ "
24 inch bins
\n",
+ "
HOWDEN TYPE
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
9/24/16
\n",
+ "
160.0
\n",
+ "
160.0
\n",
+ "
160.0
\n",
+ "
...
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
N
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
\n",
+ "
\n",
+ "
3
\n",
+ "
BALTIMORE
\n",
+ "
NaN
\n",
+ "
24 inch bins
\n",
+ "
HOWDEN TYPE
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
9/24/16
\n",
+ "
160.0
\n",
+ "
160.0
\n",
+ "
160.0
\n",
+ "
...
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
N
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
\n",
+ "
\n",
+ "
4
\n",
+ "
BALTIMORE
\n",
+ "
NaN
\n",
+ "
24 inch bins
\n",
+ "
HOWDEN TYPE
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
11/5/16
\n",
+ "
90.0
\n",
+ "
100.0
\n",
+ "
90.0
\n",
+ "
...
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
N
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
NaN
\n",
+ "
\n",
+ " \n",
+ "
\n",
+ "
5 rows × 26 columns
\n",
+ "
"
+ ],
"text/plain": [
" City Name Type Package Variety Sub Variety Grade Date \\\n",
"0 BALTIMORE NaN 24 inch bins NaN NaN NaN 4/29/17 \n",
@@ -67,17 +212,18 @@
"4 NaN NaN NaN N NaN NaN NaN \n",
"\n",
"[5 rows x 26 columns]"
- ],
- "text/html": "
 +
+This suggests that there should be some correlation, and we can try training linear regression model to predict the relationship between `Month` and `Price`, or between `DayOfYear` and `Price`. Here is the scatter plot that shows the latter relationship:
+
+
 +
+It looks like there are different clusters of prices corresponding to different pumpkin varieties. To confirm this hypothesis, let's plot each pumpkin category using a different color. By passing an `ax` parameter to the `scatter` plotting function we can plot all points on the same graph:
```python
-print(new_pumpkins['Package'].corr(new_pumpkins['Price']))
-0.6061712937226021
+ax=None
+colors = ['red','blue','green','yellow']
+for i,var in enumerate(new_pumpkins['Variety'].unique()):
+ df = new_pumpkins[new_pumpkins['Variety']==var]
+ ax = df.plot.scatter('DayOfYear','Price',ax=ax,c=colors[i],label=var)
```
-A good question to ask of this data will be: 'What price can I expect of a given pumpkin package?'
+
 -Let's build this regression model
+Our investigation suggests that variety has more effect on the overall price than the actual selling date. So let us focus for the moment only on one pumpkin variety, and see what effect the date has on the price:
+
+```python
+pie_pumpkins = new_pumpkins[new_pumpkins['Variety']=='PIE TYPE']
+pie_pumpkins.plot.scatter('DayOfYear','Price')
+```
+
 -## Building a linear model
+If we now calculate the correlation between `Price` and `DayOfYear` using `corr` function, we will get something like `-0.27` - which means that training a predictive model makes sense.
-Before building your model, do one more tidy-up of your data. Drop any null data and check once more what the data looks like.
+> Before training a linear regression model, it is important to make sure that our data is clean. Linear regression does not work well with missing values, thus it makes sense to get rid of all empty cells:
```python
-new_pumpkins.dropna(inplace=True)
-new_pumpkins.info()
+pie_pumpkins.dropna(inplace=True)
+pie_pumpkins.info()
```
-Then, create a new dataframe from this minimal set and print it out:
+Another approach would be to fill those empty values with mean values from the corresponding column.
-```python
-new_columns = ['Package', 'Price']
-lin_pumpkins = new_pumpkins.drop([c for c in new_pumpkins.columns if c not in new_columns], axis='columns')
+## Simple Linear Regression
-lin_pumpkins
-```
+To train our Linear Regression model, we will use the **Scikit-learn** library.
-```output
- Package Price
-70 0 13.636364
-71 0 16.363636
-72 0 16.363636
-73 0 15.454545
-74 0 13.636364
-... ... ...
-1738 2 30.000000
-1739 2 28.750000
-1740 2 25.750000
-1741 2 24.000000
-1742 2 24.000000
-415 rows × 2 columns
+```python
+from sklearn.linear_model import LinearRegression
+from sklearn.metrics import mean_squared_error
+from sklearn.model_selection import train_test_split
```
-1. Now you can assign your X and y coordinate data:
+We start by separating input values (features) and the expected output (label) into separate numpy arrays:
- ```python
- X = lin_pumpkins.values[:, :1]
- y = lin_pumpkins.values[:, 1:2]
- ```
-✅ What's going on here? You're using [Python slice notation](https://stackoverflow.com/questions/509211/understanding-slice-notation/509295#509295) to create arrays to populate `X` and `y`.
+```python
+X = pie_pumpkins['DayOfYear'].to_numpy().reshape(-1,1)
+y = pie_pumpkins['Price']
+```
-2. Next, start the regression model-building routines:
+> Note that we had to perform `reshape` on the input data in order for the Linear Regression package to understand it correctly. Linear Regression expects a 2D-array as an input, where each row of the array corresponds to a vector of input features. In our case, since we have only one input - we need an array with shape N×1, where N is the dataset size.
- ```python
- from sklearn.linear_model import LinearRegression
- from sklearn.metrics import r2_score, mean_squared_error, mean_absolute_error
- from sklearn.model_selection import train_test_split
+Then, we need to split the data into train and test datasets, so that we can validate our model after training:
- X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
- lin_reg = LinearRegression()
- lin_reg.fit(X_train,y_train)
+```python
+X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
+```
- pred = lin_reg.predict(X_test)
+Finally, training the actual Linear Regression model takes only two lines of code. We define the `LinearRegression` object, and fit it to our data using the `fit` method:
- accuracy_score = lin_reg.score(X_train,y_train)
- print('Model Accuracy: ', accuracy_score)
- ```
+```python
+lin_reg = LinearRegression()
+lin_reg.fit(X_train,y_train)
+```
- Because the correlation isn't particularly good, the model produced isn't terribly accurate.
+The `LinearRegression` object after `fit`-ting contains all the coefficients of the regression, which can be accessed using `.coef_` property. In our case, there is just one coefficient, which should be around `-0.017`. It means that prices seem to drop a bit with time, but not too much, around 2 cents per day. We can also access the intersection point of the regression with Y-axis using `lin_reg.intercept_` - it will be around `21` in our case, indicating the price at the beginning of the year.
- ```output
- Model Accuracy: 0.3315342327998987
- ```
+To see how accurate our model is, we can predict prices on a test dataset, and then measure how close our predictions are to the expected values. This can be done using mean square error (MSE) metrics, which is the mean of all squared differences between expected and predicted value.
-3. You can visualize the line that's drawn in the process:
+```python
+pred = lin_reg.predict(X_test)
- ```python
- plt.scatter(X_test, y_test, color='black')
- plt.plot(X_test, pred, color='blue', linewidth=3)
+mse = np.sqrt(mean_squared_error(y_test,pred))
+print(f'Mean error: {mse:3.3} ({mse/np.mean(pred)*100:3.3}%)')
+```
- plt.xlabel('Package')
- plt.ylabel('Price')
+Our error seems to be around 2 points, which is ~17%. Not too good. Another indicator of model quality is the **coefficient of determination**, which can be obtained like this:
- plt.show()
- ```
- 
+```python
+score = lin_reg.score(X_train,y_train)
+print('Model determination: ', score)
+```
+If the value is 0, it means that the model does not take input data into account, and acts as the *worst linear predictor*, which is simply a mean value of the result. The value of 1 means that we can perfectly predict all expected outputs. In our case, the coefficient is around 0.06, which is quite low.
-4. Test the model against a hypothetical variety:
+We can also plot the test data together with the regression line to better see how regression works in our case:
- ```python
- lin_reg.predict( np.array([ [2.75] ]) )
- ```
-
- The returned price for this mythological Variety is:
+```python
+plt.scatter(X_test,y_test)
+plt.plot(X_test,pred)
+```
- ```output
- array([[33.15655975]])
- ```
+
 -That number makes sense, if the logic of the regression line holds true.
-🎃 Congratulations, you just created a model that can help predict the price of a few varieties of pumpkins. Your holiday pumpkin patch will be beautiful. But you can probably create a better model!
-## Polynomial regression
+## Polynomial Regression
-Another type of linear regression is polynomial regression. While sometimes there's a linear relationship between variables - the bigger the pumpkin in volume, the higher the price - sometimes these relationships can't be plotted as a plane or straight line.
+Another type of Linear Regression is Polynomial Regression. While sometimes there's a linear relationship between variables - the bigger the pumpkin in volume, the higher the price - sometimes these relationships can't be plotted as a plane or straight line.
-✅ Here are [some more examples](https://online.stat.psu.edu/stat501/lesson/9/9.8) of data that could use polynomial regression
+✅ Here are [some more examples](https://online.stat.psu.edu/stat501/lesson/9/9.8) of data that could use Polynomial Regression
-Take another look at the relationship between Variety to Price in the previous plot. Does this scatterplot seem like it should necessarily be analyzed by a straight line? Perhaps not. In this case, you can try polynomial regression.
+Take another look at the relationship between Date and Price. Does this scatterplot seem like it should necessarily be analyzed by a straight line? Can't prices fluctuate? In this case, you can try polynomial regression.
✅ Polynomials are mathematical expressions that might consist of one or more variables and coefficients
-Polynomial regression creates a curved line to better fit nonlinear data.
-
-1. Let's recreate a dataframe populated with a segment of the original pumpkin data:
+Polynomial regression creates a curved line to better fit nonlinear data. In our case, if we include a squared `DayOfYear` variable into input data, we should be able to fit our data with a parabolic curve, which will have a minimum at a certain point within the year.
- ```python
- new_columns = ['Variety', 'Package', 'City', 'Month', 'Price']
- poly_pumpkins = new_pumpkins.drop([c for c in new_pumpkins.columns if c not in new_columns], axis='columns')
+Scikit-learn includes a helpful [pipeline API](https://scikit-learn.org/stable/modules/generated/sklearn.pipeline.make_pipeline.html?highlight=pipeline#sklearn.pipeline.make_pipeline) to combine different steps of data processing together. A **pipeline** is a chain of **estimators**. In our case, we will create a pipeline that first adds polynomial features to our model, and then trains the regression:
- poly_pumpkins
- ```
+```python
+from sklearn.preprocessing import PolynomialFeatures
+from sklearn.pipeline import make_pipeline
-A good way to visualize the correlations between data in dataframes is to display it in a 'coolwarm' chart:
+pipeline = make_pipeline(PolynomialFeatures(2), LinearRegression())
-2. Use the `Background_gradient()` method with `coolwarm` as its argument value:
+pipeline.fit(X_train,y_train)
+```
- ```python
- corr = poly_pumpkins.corr()
- corr.style.background_gradient(cmap='coolwarm')
- ```
- This code creates a heatmap:
- 
+Using `PolynomialFeatures(2)` means that we will include all second-degree polynomials from the input data. In our case it will just mean `DayOfYear`2, but given two input variables X and Y, this will add X2, XY and Y2. We may also use higher degree polynomials if we want.
-Looking at this chart, you can visualize the good correlation between Package and Price. So you should be able to create a somewhat better model than the last one.
-### Create a pipeline
+Pipelines can be used in the same manner as the original `LinearRegression` object, i.e. we can `fit` the pipeline, and then use `predict` to get the prediction results. Here is the graph showing test data, and the approximation curve:
+
+
 -Scikit-learn includes a helpful API for building polynomial regression models - the `make_pipeline` [API](https://scikit-learn.org/stable/modules/generated/sklearn.pipeline.make_pipeline.html?highlight=pipeline#sklearn.pipeline.make_pipeline). A 'pipeline' is created which is a chain of estimators. In this case, the pipeline includes polynomial features, or predictions that form a nonlinear path.
+Using Polynomial Regression, we can get slightly lower MSE and higher determination, but not significantly. We need to take into account other features!
-1. Build out the X and y columns:
+> You can see that the minimal pumpkin prices are observed somewhere around Halloween. How can you explain this?
- ```python
- X=poly_pumpkins.iloc[:,3:4].values
- y=poly_pumpkins.iloc[:,4:5].values
- ```
+🎃 Congratulations, you just created a model that can help predict the price of pie pumpkins. You can probably repeat the same procedure for all pumpkin types, but that would be tedious. Let's learn now how to take pumpkin variety into account in our model!
-2. Create the pipeline by calling the `make_pipeline()` method:
+## Categorical Features
- ```python
- from sklearn.preprocessing import PolynomialFeatures
- from sklearn.pipeline import make_pipeline
+In the ideal world, we want to be able to predict prices for different pumpkin varieties using the same model. However, the `Variety` column is somewhat different from columns like `Month`, because it contains non-numeric values. Such columns are called **categorical**.
- pipeline = make_pipeline(PolynomialFeatures(4), LinearRegression())
+Here you can see how average price depends on variety:
- X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
+
 - pipeline.fit(np.array(X_train), y_train)
+To take variety into account, we first need to convert it to numeric form, or **encode** it. There are several way we can do it:
- y_pred=pipeline.predict(X_test)
- ```
+* Simple **numeric encoding** will build a table of different varieties, and then replace the variety name by an index in that table. This is not the best idea for linear regression, because linear regression takes the actual numeric value of the index, and adds it to the result, multiplying by some coefficient. In our case, the relationship between the index number and the price is clearly non-linear, even if we make sure that indices are ordered in some specific way.
+* **One-hot encoding** will replace the `Variety` column by 4 different columns, one for each variety. Each column will contain `1` if the corresponding row is of a given variety, and `0` otherwise. This means that there will be four coefficients in linear regression, one for each pumpkin variety, responsible for "starting price" (or rather "additional price") for that particular variety.
-### Create a sequence
+The code below shows how we can one-hot encode a variety:
-At this point, you need to create a new dataframe with _sorted_ data so that the pipeline can create a sequence.
+```python
+pd.get_dummies(new_pumpkins['Variety'])
+```
-Add the following code:
+ ID | FAIRYTALE | MINIATURE | MIXED HEIRLOOM VARIETIES | PIE TYPE
+----|-----------|-----------|--------------------------|----------
+70 | 0 | 0 | 0 | 1
+71 | 0 | 0 | 0 | 1
+... | ... | ... | ... | ...
+1738 | 0 | 1 | 0 | 0
+1739 | 0 | 1 | 0 | 0
+1740 | 0 | 1 | 0 | 0
+1741 | 0 | 1 | 0 | 0
+1742 | 0 | 1 | 0 | 0
- ```python
- df = pd.DataFrame({'x': X_test[:,0], 'y': y_pred[:,0]})
- df.sort_values(by='x',inplace = True)
- points = pd.DataFrame(df).to_numpy()
+To train linear regression using one-hot encoded variety as input, we just need to initialize `X` and `y` data correctly:
- plt.plot(points[:, 0], points[:, 1],color="blue", linewidth=3)
- plt.xlabel('Package')
- plt.ylabel('Price')
- plt.scatter(X,y, color="black")
- plt.show()
- ```
+```python
+X = pd.get_dummies(new_pumpkins['Variety'])
+y = new_pumpkins['Price']
+```
-You created a new dataframe by calling `pd.DataFrame`. Then you sorted the values by calling `sort_values()`. Finally you created a polynomial plot:
+The rest of the code is the same as what we used above to train Linear Regression. If you try it, you will see that the mean squared error is about the same, but we get much higher coefficient of determination (~77%). To get even more accurate predictions, we can take more categorical features into account, as well as numeric features, such as `Month` or `DayOfYear`. To get one large array of features, we can use `join`:
-
+```python
+X = pd.get_dummies(new_pumpkins['Variety']) \
+ .join(new_pumpkins['Month']) \
+ .join(pd.get_dummies(new_pumpkins['City'])) \
+ .join(pd.get_dummies(new_pumpkins['Package']))
+y = new_pumpkins['Price']
+```
-You can see a curved line that fits your data better.
+Here we also take into account `City` and `Package` type, which gives us MSE 2.84 (10%), and determination 0.94!
-Let's check the model's accuracy:
+## Putting it all together
- ```python
- accuracy_score = pipeline.score(X_train,y_train)
- print('Model Accuracy: ', accuracy_score)
- ```
+To make the best model, we can use combined (one-hot encoded categorical + numeric) data from the above example together with Polynomial Regression. Here is the complete code for your convenience:
- And voila!
+```python
+# set up training data
+X = pd.get_dummies(new_pumpkins['Variety']) \
+ .join(new_pumpkins['Month']) \
+ .join(pd.get_dummies(new_pumpkins['City'])) \
+ .join(pd.get_dummies(new_pumpkins['Package']))
+y = new_pumpkins['Price']
- ```output
- Model Accuracy: 0.8537946517073784
- ```
+# make train-test split
+X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
-That's better! Try to predict a price:
+# setup and train the pipeline
+pipeline = make_pipeline(PolynomialFeatures(2), LinearRegression())
+pipeline.fit(X_train,y_train)
-### Do a prediction
+# predict results for test data
+pred = pipeline.predict(X_test)
-Can we input a new value and get a prediction?
+# calculate MSE and determination
+mse = np.sqrt(mean_squared_error(y_test,pred))
+print(f'Mean error: {mse:3.3} ({mse/np.mean(pred)*100:3.3}%)')
-Call `predict()` to make a prediction:
-
- ```python
- pipeline.predict( np.array([ [2.75] ]) )
- ```
- You are given this prediction:
+score = pipeline.score(X_train,y_train)
+print('Model determination: ', score)
+```
- ```output
- array([[46.34509342]])
- ```
+This should give us the best determination coefficient of almost 97%, and MSE=2.23 (~8% prediction error).
-It does make sense, given the plot! And, if this is a better model than the previous one, looking at the same data, you need to budget for these more expensive pumpkins!
+| Model | MSE | Determination |
+|-------|-----|---------------|
+| `DayOfYear` Linear | 2.77 (17.2%) | 0.07 |
+| `DayOfYear` Polynomial | 2.73 (17.0%) | 0.08 |
+| `Variety` Linear | 5.24 (19.7%) | 0.77 |
+| All features Linear | 2.84 (10.5%) | 0.94 |
+| All features Polynomial | 2.23 (8.25%) | 0.97 |
-🏆 Well done! You created two regression models in one lesson. In the final section on regression, you will learn about logistic regression to determine categories.
+🏆 Well done! You created four Regression models in one lesson, and improved the model quality to 97%. In the final section on Regression, you will learn about Logistic Regression to determine categories.
---
## 🚀Challenge
diff --git a/2-Regression/3-Linear/images/linear-results.png b/2-Regression/3-Linear/images/linear-results.png
new file mode 100644
index 000000000..05abe0025
Binary files /dev/null and b/2-Regression/3-Linear/images/linear-results.png differ
diff --git a/2-Regression/3-Linear/images/pie-pumpkins-scatter.png b/2-Regression/3-Linear/images/pie-pumpkins-scatter.png
new file mode 100644
index 000000000..f0a2af56b
Binary files /dev/null and b/2-Regression/3-Linear/images/pie-pumpkins-scatter.png differ
diff --git a/2-Regression/3-Linear/images/poly-results.png b/2-Regression/3-Linear/images/poly-results.png
new file mode 100644
index 000000000..6d1e96336
Binary files /dev/null and b/2-Regression/3-Linear/images/poly-results.png differ
diff --git a/2-Regression/3-Linear/images/price-by-variety.png b/2-Regression/3-Linear/images/price-by-variety.png
new file mode 100644
index 000000000..e5a15ca34
Binary files /dev/null and b/2-Regression/3-Linear/images/price-by-variety.png differ
diff --git a/2-Regression/3-Linear/images/scatter-dayofyear-color.png b/2-Regression/3-Linear/images/scatter-dayofyear-color.png
new file mode 100644
index 000000000..499b6f6dd
Binary files /dev/null and b/2-Regression/3-Linear/images/scatter-dayofyear-color.png differ
diff --git a/2-Regression/3-Linear/images/scatter-dayofyear.png b/2-Regression/3-Linear/images/scatter-dayofyear.png
new file mode 100644
index 000000000..d37356c25
Binary files /dev/null and b/2-Regression/3-Linear/images/scatter-dayofyear.png differ
diff --git a/2-Regression/3-Linear/notebook.ipynb b/2-Regression/3-Linear/notebook.ipynb
index adcbbce3a..2da56e5b6 100644
--- a/2-Regression/3-Linear/notebook.ipynb
+++ b/2-Regression/3-Linear/notebook.ipynb
@@ -1,28 +1,8 @@
{
- "metadata": {
- "language_info": {
- "codemirror_mode": {
- "name": "ipython",
- "version": 3
- },
- "file_extension": ".py",
- "mimetype": "text/x-python",
- "name": "python",
- "nbconvert_exporter": "python",
- "pygments_lexer": "ipython3",
- "version": "3.8.3-final"
- },
- "orig_nbformat": 2,
- "kernelspec": {
- "name": "python3",
- "display_name": "Python 3",
- "language": "python"
- }
- },
- "nbformat": 4,
- "nbformat_minor": 2,
"cells": [
{
+ "cell_type": "markdown",
+ "metadata": {},
"source": [
"## Pumpkin Pricing\n",
"\n",
@@ -32,9 +12,7 @@
"- Convert the date to a month\n",
"- Calculate the price to be an average of high and low prices\n",
"- Convert the price to reflect the pricing by bushel quantity"
- ],
- "cell_type": "markdown",
- "metadata": {}
+ ]
},
{
"cell_type": "code",
@@ -42,8 +20,175 @@
"metadata": {},
"outputs": [
{
- "output_type": "execute_result",
"data": {
+ "text/html": [
+ "